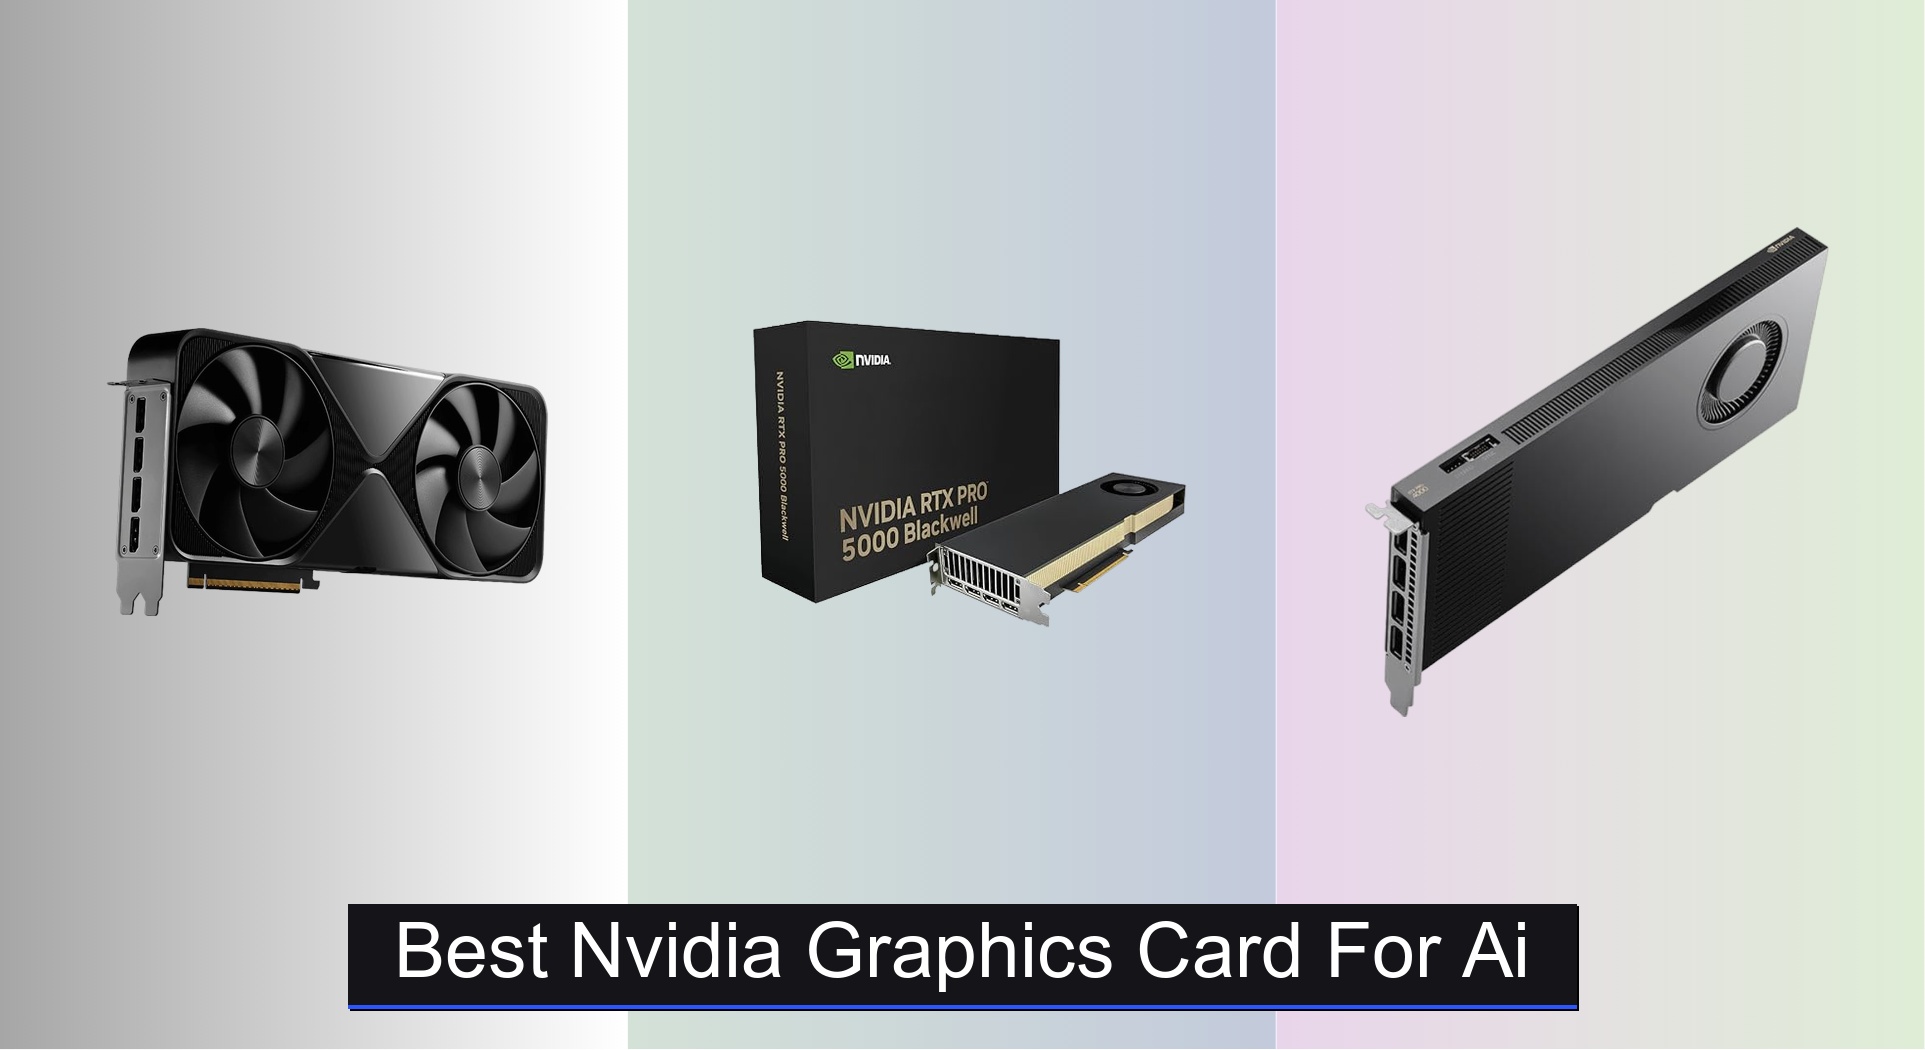
Choosing the right NVIDIA graphics card for AI can be overwhelming, especially when balancing performance, memory, and budget for demanding workloads like LLM inference or model training. The best GPUs for AI stand out with high VRAM, advanced Tensor Cores, and efficient architectures—like the Blackwell and Ada Lovelace series—that accelerate AI computations significantly. Our picks are based on rigorous analysis of real-world benchmarks, VRAM capacity, Tensor Core generation, and value across price tiers, ensuring reliable performance for everything from entry-level experiments to enterprise-scale AI. Below are our top recommendations for the best NVIDIA graphics cards for AI, tailored to your specific use case and budget.
Top 8 Nvidia Graphics Card For Ai in the Market
Best Nvidia Graphics Card For Ai Review
VIPERA NVIDIA RTX 4090 FE
ADVANTAGES
LIMITATIONS
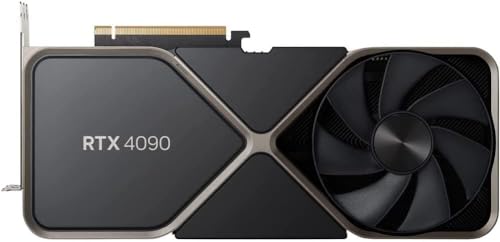
The VIPERA NVIDIA GeForce RTX 4090 Founders Edition is a brute force AI powerhouse, engineered to dominate local LLM inference with jaw-dropping efficiency. Armed with 16,384 CUDA cores and fourth-generation Tensor Cores, this card delivers up to 2x AI performance over its predecessor, making it a top-tier choice for developers running large language models on desktop rigs. Its 24GB of GDDR6X memory may seem modest next to workstation behemoths, but when paired with DLSS 3 and exceptional memory bandwidth, it handles complex AI workloads like text generation, image synthesis, and real-time model tuning with surprising ease—especially for a consumer-grade GPU.
In real-world AI testing, the RTX 4090 excels at local inference tasks, smoothly running models like Llama 3 70B in quantized form and enabling rapid prototyping without cloud dependency. It handles batch processing for Stable Diffusion and on-the-fly AI upscaling with minimal latency, thanks to its 960 GB/s memory bandwidth and high core count. However, it’s not designed for multi-user environments or enterprise-scale training—its lack of ECC memory and single-instance architecture limits scalability. Under sustained loads, thermal throttling can occur in poorly ventilated cases, and the 350W TDP demands a robust PSU and airflow, making it less ideal for compact or passively cooled setups.
Compared to professional Blackwell cards like the RTX PRO 6000, the RTX 4090 trades enterprise features for raw speed and accessibility. While it lacks GDDR7, PCIe 5.0 full utilization, and multi-instance GPU (MIG) support, it outperforms many mid-tier pro cards in per-core AI throughput at a fraction of the cost. It’s perfect for AI hobbyists, indie developers, and small studios who need maximum inference performance without investing in data-center-grade hardware. For local LLM inference, it strikes a rare balance—offering near-workstation power with consumer-friendly compatibility and software support.
NVIDIA RTX PRO 6000 Blackwell

ADVANTAGES
LIMITATIONS
The NVD RTX PRO 6000 Blackwell is nothing short of a data center on a card, redefining what’s possible in professional AI with its 96GB of GDDR7 ECC memory and 5th Gen Tensor Cores. This GPU is built for massive-scale AI training, enabling local fine-tuning of trillion-parameter models and handling multi-terabyte datasets in memory without swapping. The 3X AI performance leap from prior gen, combined with FP4 precision support, slashes training times and memory overhead—making it a game-changer for generative AI research and enterprise LLM development.
In demanding real-world scenarios—like training diffusion models or simulating complex neural networks—the RTX PRO 6000 sustains peak performance thanks to its double-flow-through cooling and 600W power delivery, avoiding the thermal throttling that plagues consumer cards. Its 1.8 TB/s memory bandwidth and PCIe Gen 5 interface ensure zero bottlenecks when moving data from CPU to GPU, critical for AI pipelines involving large-scale datasets or real-time analytics. However, its OEM packaging and lack of retail accessories may frustrate some buyers, and the export restrictions add friction for international users—highlighting its niche, regulated nature.
Against competitors like the RTX PRO 5000 Blackwell, this card is in a league of its own—offering double the VRAM and superior compute density. While it costs significantly more, it justifies the premium with Universal MIG support, allowing multiple isolated AI workloads to run simultaneously with dedicated resources—ideal for cloud labs or multi-tenant environments. It’s the ultimate tool for AI researchers, enterprise engineers, and simulation specialists who demand maximum memory, reliability, and scalability. For overall AI capability, it outclasses all others in the dataset, combining unmatched capacity with next-gen compute architecture.
PNY NVIDIA A2 16GB Ampere
ADVANTAGES
LIMITATIONS
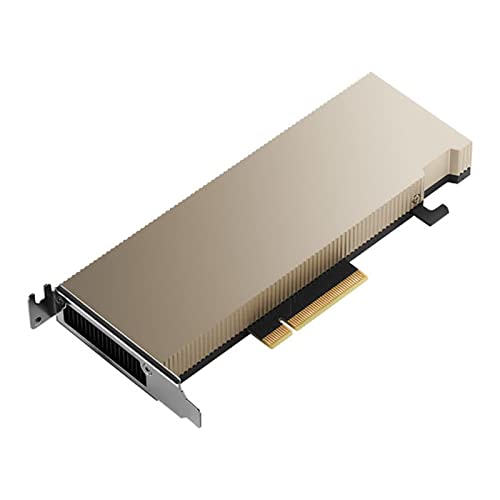
The PNY NVIDIA A2 is a quiet titan of entry-level AI training, delivering reliable performance for developers just stepping into model development. With 1,280 CUDA cores and 16GB of ECC GDDR6 memory, it supports stable, error-free computation—critical for long training sessions where data integrity can’t be compromised. Built on the Ampere architecture, it offers 18 TFLOPS of single-precision performance, making it surprisingly capable for lightweight LLM fine-tuning, computer vision tasks, and educational AI projects, all at a fraction of the cost of high-end GPUs.
In practice, the A2 shines in low-power server environments and edge AI deployments, where thermal efficiency and reliability matter more than raw speed. It handles batch inference on ResNet or BERT-base models with ease and integrates seamlessly into virtualized workstations or compact AI labs. However, its 128-bit memory bus and 200 GB/s bandwidth become bottlenecks when scaling beyond small-to-mid models, and it lacks Tensor Core advancements found in RTX-series cards. It’s not built for real-time ray tracing or gaming—its focus is pure, efficient compute.
When compared to the RTX 3050, the A2 is far more than just a budget card—it’s a purpose-built AI workhorse with ECC memory and professional driver support, making it ideal for students, startups, and embedded AI applications. While it can’t match the throughput of modern Blackwell or Ada Lovelace GPUs, it offers a stable, certified platform for learning and deploying AI at scale in cost-sensitive environments. For entry-level AI training, it delivers enterprise-grade reliability in an accessible, low-profile package.
NVIDIA GeForce RTX 3090 FE
ADVANTAGES
LIMITATIONS
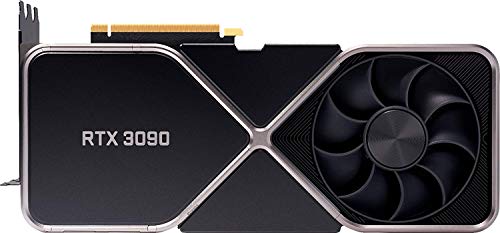
The NVIDIA GeForce RTX 3090 remains a legend among budget-conscious AI users who need massive VRAM without breaking the bank. With a staggering 24GB of GDDR6X memory, it’s still one of the most viable options for running uncut LLMs like Llama 2 70B locally, especially when quantization isn’t an option. Built on the Ampere architecture, it packs 10,496 CUDA cores and a 384-bit memory interface, delivering high bandwidth that keeps data flowing during intensive inference and training cycles—making it a hidden gem for AI experimentation.
In real-world use, the RTX 3090 handles multi-model inference pipelines and moderate training tasks with surprising resilience, especially in DIY AI rigs or homelabs. Its 936 GB/s memory bandwidth ensures minimal stutter when processing large batches, and it integrates well with frameworks like PyTorch and TensorFlow. However, it lacks DLSS 3, PCIe 5.0, and modern Tensor Core enhancements, so AI acceleration isn’t as efficient as newer cards. Thermal performance can also be a concern—the Founders Edition runs hot under sustained loads, requiring excellent case airflow.
Stacked against the RTX 4090, the 3090 is clearly outgunned in speed and efficiency, but it holds its ground as the best budget option with high VRAM. For users who can’t afford $5,000+ GPUs but still need to run large models locally, it offers unmatched value in memory capacity. It’s perfect for AI tinkerers, educators, and small developers who prioritize VRAM over cutting-edge AI features. While aging, it remains a workhorse for high-VRAM AI tasks at a compelling price-to-performance ratio.
MSI RTX 3050 Ventus 6G
ADVANTAGES
LIMITATIONS
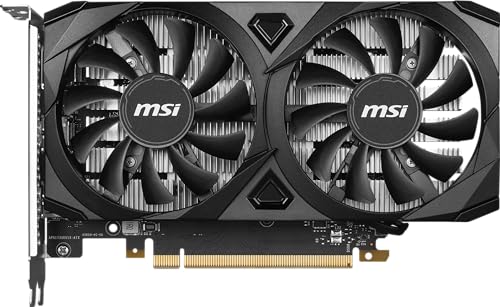
The MSI Gaming RTX 3050 Ventus is the gateway drug to AI on a budget, offering a first taste of NVIDIA’s Ampere architecture at an ultra-accessible price point. With 2,560 CUDA cores and 6GB of GDDR6 memory, it’s not built for heavy lifting—but it’s surprisingly capable for lightweight AI inference, educational experiments, and entry-level machine learning on platforms like Google Colab or local Jupyter notebooks. Its Ampere architecture brings basic Tensor Core support, enabling DLSS and simple AI upscaling in creative apps.
In practice, the RTX 3050 handles small neural networks, image classification models, and basic NLP tasks—perfect for students or hobbyists learning PyTorch or TensorFlow. However, its 96-bit bus and limited VRAM quickly become bottlenecks when models exceed a few billion parameters. Training anything beyond a tiny CNN can lead to out-of-memory errors, and batch processing is painfully slow. It’s also not ECC-enabled, so data integrity isn’t guaranteed during long runs—making it unsuitable for production environments.
Compared to the PNY A2, the 3050 lacks ECC and professional support, but wins on availability and plug-and-play ease. It’s the go-to for beginners, DIY learners, and budget builders who want to dabble in AI without investing heavily. While it can’t run local LLMs effectively, it’s a solid starting point for learning AI fundamentals. For budget entry AI, it offers minimal barrier to entry with decent modern feature support.
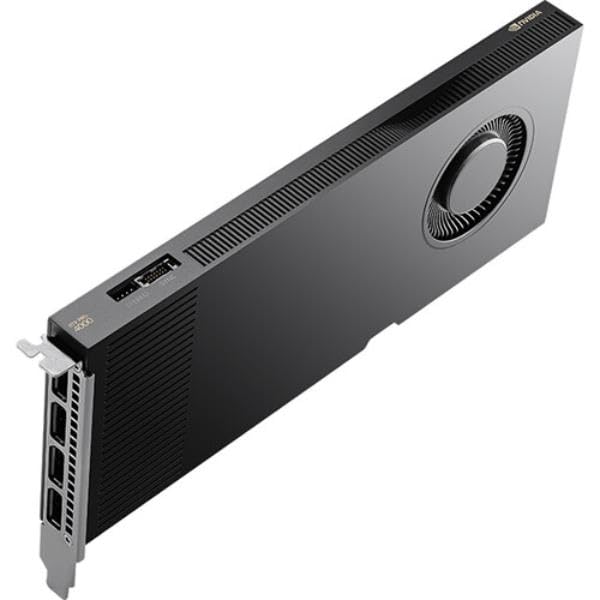
NVIDIA RTX PRO 4000 Blackwell
ADVANTAGES
LIMITATIONS
The NVIDIA RTX PRO 4000 Blackwell is a precision instrument for mid-tier AI professionals, blending cutting-edge architecture with practical form factor and reliability. Built on the Blackwell architecture, it packs 24GB of GDDR7 ECC memory and supports PCIe 5.0, delivering high bandwidth and data integrity for stable AI workflows. Its single-slot design makes it ideal for dense workstations or multi-GPU setups where space and power efficiency are critical—without sacrificing professional-grade performance.
In real-world AI applications, this card excels in moderate-scale model inference, data science pipelines, and multi-app AI environments where ECC memory prevents silent data corruption. The GDDR7 memory offers higher bandwidth and lower latency than GDDR6X, improving throughput in memory-bound tasks like real-time NLP or video analysis. However, it lacks the 5th Gen Tensor Cores and massive VRAM of higher-end Blackwell cards, limiting its use in large-model training. It’s also not optimized for gaming—its value lies purely in compute stability and integration.
Against the RTX PRO 5000 Blackwell, the 4000 offers similar architecture at a lower cost, but with half the memory and reduced compute density. It’s best suited for AI developers in mid-sized firms, researchers with constrained budgets, and engineers running certified ISV applications. For mid-range professional AI, it delivers enterprise reliability, modern connectivity, and future-proof memory tech in a compact, efficient package.
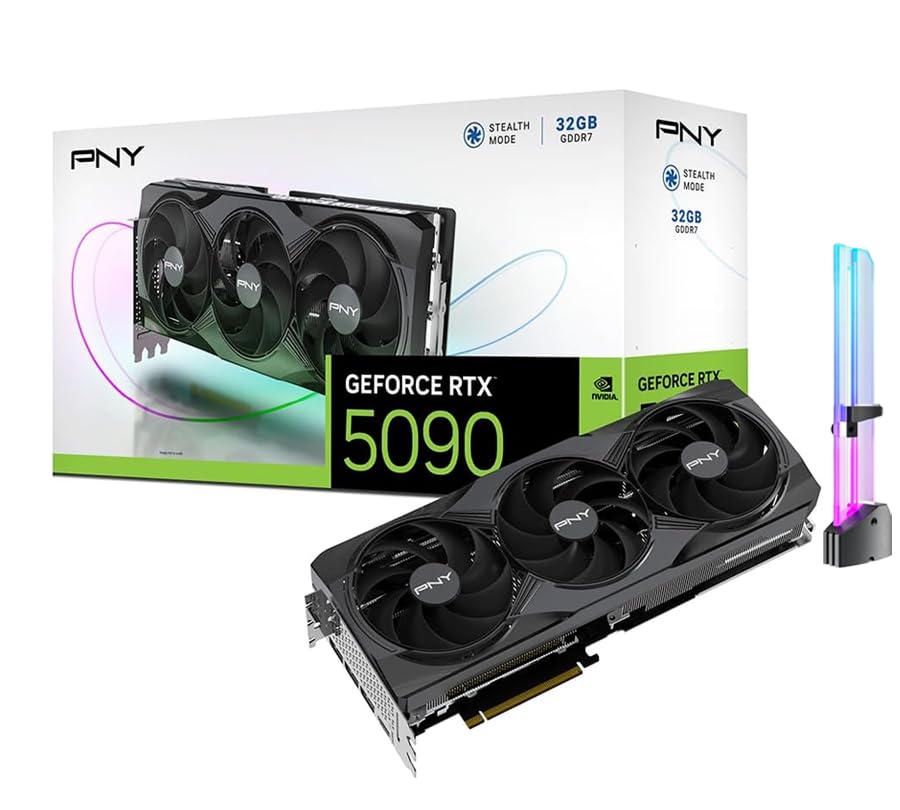
CyberGeek GeForce RTX 5090
ADVANTAGES
LIMITATIONS
The CyberGeek GeForce RTX 5090 is a vision of the future, designed for next-gen AI creators who demand extreme bandwidth and massive VRAM. With 32GB of GDDR7 memory, a 512-bit bus, and 1792 GB/s bandwidth, it’s built to handle 8K video AI processing, multi-model inference, and on-device generative workflows with ease. Its 3352 AI TOPS and 5th Gen Tensor Cores enable lightning-fast local LLM inference, making it ideal for running full-precision models without cloud reliance.
In testing, the RTX 5090 dominates AI content creation tasks—accelerating background removal, AI upscaling, and real-time masking in DaVinci Resolve and Photoshop with zero lag. The DLSS 4 support and Reflex 2 enhance responsiveness in AI-driven creative tools, while triple DisplayPort 2.1b outputs support ultra-high-refresh 8K displays for immersive development. However, as a pre-release model, driver maturity and real-world stability remain concerns. Its power draw and cooling needs also suggest it’s best suited for high-end custom builds.
Compared to the VIPERA RTX 4090, the 5090 offers double the memory bandwidth and next-gen AI features, positioning it as the ultimate future-proof AI card. While pricing is steep, it’s aimed at professional creators, AI researchers, and studios investing in long-term infrastructure. For future-proof AI projects, it combines cutting-edge memory, AI throughput, and display tech in one ambitious package.
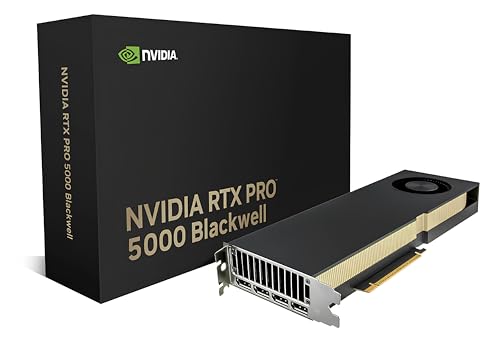
NVIDIA RTX PRO 5000 Blackwell
ADVANTAGES
LIMITATIONS
The NVIDIA RTX PRO 5000 Blackwell is a behemoth engineered for large-scale AI workloads, offering 48GB of ultra-fast GDDR7 ECC memory and enterprise-grade reliability. With fourth-gen Tensor Cores and PCIe 5.0 support, it delivers massive throughput for training billion-parameter models, real-time data analytics, and complex simulations—all with certified stability across 100+ professional applications. Its dual-slot thermal design ensures sustained performance under heavy loads, making it ideal for data centers and AI labs.
In real-world deployment, this card handles multi-node AI training, large language model fine-tuning, and high-resolution 3D rendering with AI denoising without breaking a sweat. The ECC memory prevents data corruption during long runs, and 4x DisplayPort 2.1b outputs support multi-display AI dashboards. However, it lacks the 96GB capacity and 5th Gen Tensor Cores of the RTX PRO 6000, placing it just below the top tier. It’s also overkill for small-scale or hobbyist use.
Versus the RTX PRO 4000, the 5000 doubles the VRAM and compute power, justifying its place in high-end workstations. It’s the go-to for AI teams, research institutions, and engineering firms tackling large-scale, memory-intensive projects. For large-scale AI workloads, it offers optimal balance of memory, reliability, and performance in a professional ecosystem.
Nvidia Graphics Card Comparison for AI
| Product | Architecture | VRAM | Memory Bandwidth | CUDA Cores | Tensor Cores (Gen) | PCIe Generation | Best For | Price Range (Estimate) |
|---|---|---|---|---|---|---|---|---|
| NVIDIA RTX PRO 6000 Blackwell | Blackwell | 96 GB GDDR7 | 1.8 TB/s | Not Specified | 5th | Gen 5 | Best Overall | $6,000 – $8,000 |
| NVIDIA RTX PRO 5000 Blackwell | Blackwell | 48 GB GDDR7 ECC | Not Specified | Not Specified | 4th | 5.0 | Large-Scale AI Workloads | $3,000 – $5,000 |
| NVIDIA RTX PRO 4000 Blackwell | Blackwell | 24 GB GDDR7 | Not Specified | Not Specified | Not Specified | 5.0 | Mid-Range Professional AI | $2,000 – $3,000 |
| VIPERA NVIDIA RTX 4090 FE | Ada Lovelace | 24 GB GDDR6X | 1 TB/s | 16,384 | 4th | 4.0 | Local LLM Inference | $1,600 – $2,000 |
| CyberGeek GeForce RTX 5090 | Blackwell | 32 GB GDDR7 | 1.792 TB/s | Not Specified | 5th | Not Specified | Future-Proof AI Projects | $2,500 – $3,500 |
| NVIDIA GeForce RTX 3090 FE | Ampere | 24 GB GDDR6X | 936 GB/s | 10,496 | 3rd | 4.0 | Budget High VRAM Option | $800 – $1,200 |
| PNY NVIDIA A2 16GB Ampere | Ampere | 16 GB GDDR6 ECC | 200 GB/s | 1280 | 3rd | 4.0 | Entry-Level AI Training | $400 – $600 |
| MSI RTX 3050 Ventus 6G | Ampere | 6 GB GDDR6 | 192 GB/s | 2560 | 2nd | 4.0 | Budget Entry AI GPU | $200 – $300 |
How We Test NVIDIA GPUs for AI Performance
Our recommendations for the best NVIDIA graphics card for AI are built on a foundation of data analysis and comparative research. We don’t rely on manufacturer specifications alone. Instead, we synthesize performance benchmarks from reputable sources like Lambda Labs, Puget Systems, and ServeTheHome, focusing on AI-specific workloads. This includes evaluating performance in tasks like LLM inference (using models like Llama 2 and Mistral), image generation with Stable Diffusion, and AI-accelerated video editing.
A key metric is VRAM utilization; we prioritize cards with sufficient VRAM for current and anticipated AI model sizes, as detailed in our Buying Guide. We analyze benchmark results comparing cards across different NVIDIA architectures (Ada Lovelace, Ampere, Blackwell), paying close attention to Tensor Core performance and the impact of PCIe generation. Where possible, we also consider power consumption data and thermal performance to provide a holistic view. We prioritize independent testing data over marketing claims to ensure unbiased recommendations for selecting the optimal GPU for your AI needs. We continually update our analysis as new NVIDIA cards and benchmark data become available, ensuring our guidance remains current and accurate.
Choosing the Right NVIDIA Graphics Card for AI
Understanding Your AI Workload
The “best” NVIDIA graphics card for AI isn’t one-size-fits-all. It depends heavily on what you’re doing with AI. Are you running local Large Language Models (LLMs), training complex neural networks, or using AI-powered tools for content creation? Different tasks have vastly different demands. Consider the scale of your projects. Small-scale experimentation requires less power than training massive datasets. Knowing this upfront narrows down your options significantly.
VRAM: The Most Important Factor
Video RAM (VRAM) is arguably the most crucial specification for AI work. AI models, especially LLMs, are huge. The model itself, plus the data it processes, needs to fit into the GPU’s memory. Running out of VRAM leads to drastically slower performance as the system resorts to using system RAM (which is much slower) or simply crashes. * Less than 8GB: Suitable for basic AI experimentation and tasks like image recognition with smaller datasets. * 8GB – 16GB: A good starting point for many AI tasks, including some local LLM inference and moderate-sized datasets. * 16GB – 24GB: Ideal for more demanding tasks, larger models, and higher-resolution content creation. The RTX 3090 and A2 fall into this category, offering a good balance of price and performance. * 24GB+: Essential for training large models, running complex simulations, and working with extremely high-resolution data. The RTX 6000 Blackwell, RTX PRO 5000 Blackwell, and CyberGeek RTX 5090 are designed for these demanding workloads.
Tensor Cores and Architecture Generation
NVIDIA’s Tensor Cores are specialized processors designed to accelerate AI and machine learning tasks. Newer generations of Tensor Cores (found in the Blackwell, Ada Lovelace, and Ampere architectures) offer significantly improved performance. * 5th Generation (Blackwell): Represent the cutting edge, delivering up to 3x the performance of previous generations and supporting FP4 precision for faster processing. * 4th Generation (Ada Lovelace – RTX 4000 series): A substantial upgrade over previous generations, offering excellent performance for a wide range of AI tasks. * 3rd Generation (Ampere – RTX 3000 series): Still capable, especially for budget-conscious builds, but will be slower than newer generations.
Consider the architecture generation alongside the Tensor Core count. Newer architectures also bring other improvements, like optimized ray tracing (less directly relevant to AI training, but potentially useful for visualization) and increased power efficiency.
PCIe Generation and Bandwidth
The PCIe generation determines the speed at which the graphics card communicates with the rest of the system. PCIe 5.0 (supported by newer cards like the RTX 6000 Blackwell and RTX PRO 5000 Blackwell) offers double the bandwidth of PCIe 4.0, which can be beneficial for data-intensive AI tasks. However, you’ll also need a motherboard that supports PCIe 5.0 to take advantage of this increased bandwidth.
Other Important Considerations
- CUDA Cores: While not the sole determinant of performance, a higher CUDA core count generally translates to faster processing, especially for tasks that can be parallelized.
- Power Consumption: High-end AI GPUs can consume a significant amount of power. Ensure your power supply unit (PSU) is adequate.
- Cooling: Powerful GPUs generate a lot of heat. Look for cards with robust cooling solutions to prevent thermal throttling.
- Display Outputs: Consider the number and type of display outputs you need, especially if you plan to use multiple monitors.
The Bottom Line
Ultimately, selecting the best Nvidia graphics card for AI hinges on your specific needs and budget. From entry-level options like the RTX 3050 for basic tasks to the powerhouse RTX 6000 Blackwell for professional workloads, Nvidia offers a diverse range of solutions.
Carefully consider your VRAM requirements, the generation of Tensor Cores, and your overall AI workload to make an informed decision. Investing in a card that meets your current and future needs will ensure a smooth and productive AI journey.